HKEx Filings
io.github.simonmak-ascent/hkex-filings · 16 stars · Python · MIT
MCP server Live HKEx (Hong Kong Stock Exchange) regulatory filings for AI agents.
Install
The repo has no one-line install. Follow its README.
Published as
- PyPI
hkex-filing-scraperstdio - Remote
https://hkex-listco-updates.ascent-partners.com/api/mcpStreamable HTTP
From the server's entry in the official MCP Registry.
Files
HKEx Filing Scraper
An open-source scraper for 25+ years of HKEx regulatory filings — into any of nine databases, with full-text extraction, graph linking, and a read-only MCP server for AI agents.

Overview
The US has EDGAR full-text search. Japan has EDINET. Hong Kong has a search form that returns one page at a time. There is no bulk, machine-readable, full-text corpus of HKEx filings. This builds one.
An open-source Python tool that scrapes 25+ years of Hong Kong Stock Exchange (HKEx) regulatory filings and ingests them into any combination of nine databases — with full-text and table extraction, chunk-level coverage, optional graph linking, and a read-only MCP server so AI agents can query the corpus or the live site.
It speaks the undocumented HKEx JSON API directly, which is faster and more resilient than driving a browser.
Vendors & Integrations
Databases — nine first-class destinations, in documented popularity order (see the support matrix):
- PostgreSQL — production-grade open-source relational
- MySQL / MariaDB — GPL relational servers, one driver
- SQLite — zero-server file database, no install needed
- MongoDB — document database
- Neo4j — property-graph database
- ClickHouse — columnar analytics engine
- DuckDB — in-process analytical engine
- SurrealDB — multi-model graph + document database
AI clients — any MCP-capable agent; ready-made configuration for Claude, ChatGPT, Cursor, VS Code/Copilot, Gemini CLI, opencode, Manus, and Perplexity.
Available on — PyPI · Glama · MCP Registry · hosted gateway.
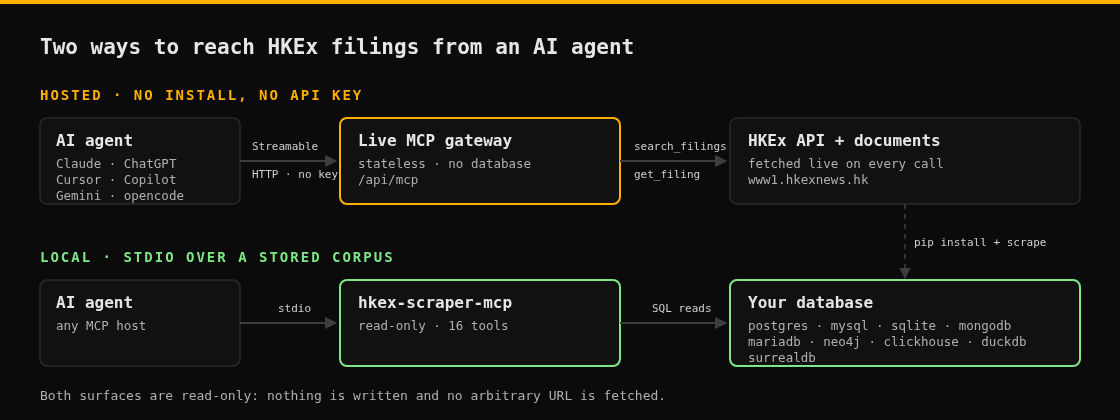
Two Ways to Use It
| Hosted MCP gateway | Local pipeline | |
|---|---|---|
| What | A public endpoint you point an AI agent at | The hkex-scraper CLI |
| Setup | None — paste a URL | pip install + one environment variable |
| Data | Live from HKEx, nothing stored | Stored in your database(s) |
| Docs | Live MCP gateway · AI agent support | Getting started |
Use the Hosted MCP Gateway
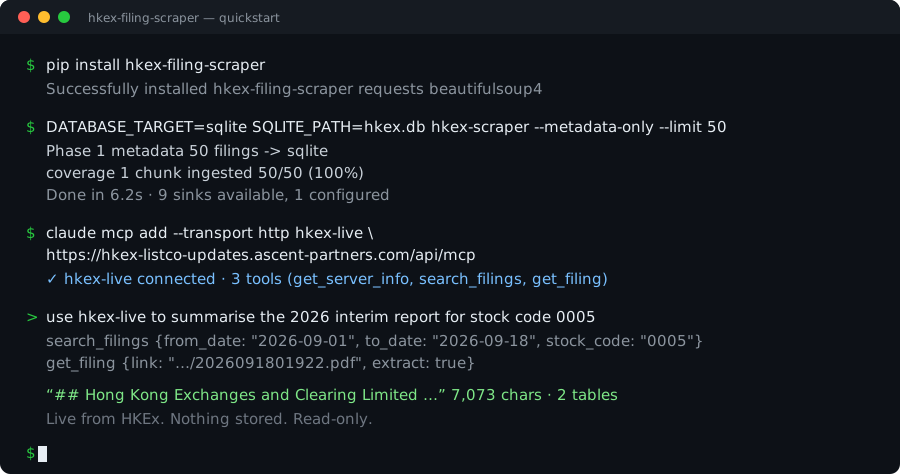
POST, Streamable HTTP, no API key:
https://hkex-listco-updates.ascent-partners.com/api/mcp
Four read-only tools: get_server_info, search_filings (a window of at most 31 days, with
optional stock-code, title, document-type, category, and stock-name filters),
list_filing_facets (browse what a window contains), and get_filing (downloads one
document and extracts its text and tables).
Point a client at it — for example opencode:
{
  "$schema": "https://opencode.ai/config.json",
  "mcp": {
    "hkex-live": {
      "type": "remote",
      "url": "https://hkex-listco-updates.ascent-partners.com/api/mcp"
    }
  }
}
Then ask:
Use hkex-live to list the filings published between 2026-09-01 and 2026-09-18,
then summarise the interim report.
Ready-made configuration for Claude, ChatGPT, Cursor, VS Code/Copilot, Gemini CLI, opencode,
Manus, and Perplexity is in AI agent support — and for a stored corpus,
the stdio MCP server exposes a wider tool catalog and is published on
Glama. The gateway is listed
in the official MCP Registry as
io.github.simonmak-ascent/hkex-filings.
Featured on Glama — the read-only stdio MCP server is also published on Glama, where Glama scans the built server and scores tool-definition quality (currently 4.7/5).
Quick Start (≤ 5 minutes)
Fastest path: no install — use the hosted gateway at
https://hkex-listco-updates.ascent-partners.com/api/mcp (Streamable HTTP), or install and run
locally:
pip install hkex-filing-scraper        # core; SQLite needs no server
pip install "hkex-filing-scraper[all]" # Excel + dotenv + every driver + the MCP server
cp .env.example .env                   # then set DATABASE_TARGET (below)
hkex-scraper --metadata-only --limit 100
Optional extras: excel, postgres, mysql, duckdb, mongodb, clickhouse, neo4j,
mcp, pdf, all, dev.
DATABASE_TARGET is an ordered, comma-separated list of sink ids; the order decides which
sink serves reads. To start with no server:
DATABASE_TARGET=sqlite
SQLITE_PATH=hkex.db
hkex-scraper runs the full pipeline (metadata + documents + graph); hkex-scraper --full-history covers everything since April 1999. The schema is created automatically.
Full install options and per-sink settings are in Getting started.
Database Support
Every sink is a first-class destination; rows are in documented popularity order. The full matrix — licenses, capability differences, per-engine notes — is in Database sinks.
| Sink | Model | License | Extra | Idempotent upsert |
|---|---|---|---|---|
postgres |
relational | PostgreSQL License | postgres |
ON CONFLICT DO UPDATE |
mysql / mariadb |
relational | GPLv2 | mysql |
ON DUPLICATE KEY UPDATE |
sqlite |
relational | Public domain | — | ON CONFLICT DO UPDATE |
mongodb |
document | SSPL¹ | mongodb |
update_one(upsert=True) |
neo4j |
graph | GPLv3 (Community) | neo4j |
MERGE |
clickhouse |
columnar | Apache-2.0 | clickhouse |
ReplacingMergeTree + read-merge |
duckdb |
relational | MIT | duckdb |
ON CONFLICT DO UPDATE |
surrealdb |
graph + document | BSL 1.1¹ | — | UPSERT / RELATE |
¹ Source-available, not OSI-approved — labeled exceptions per ADR 0003.
Valid sink ids, in documented order: postgres, mysql, sqlite, mongodb, mariadb, neo4j, clickhouse, duckdb, surrealdb. Set one variable and the same run feeds every sink:
# Order sets read precedence.
DATABASE_TARGET=postgres,sqlite
POSTGRES_DSN=postgresql://user:password@localhost:5432/hkex
SQLITE_PATH=hkex.db
How This Compares
Four ways to get HKEx filings, and what each one costs you.
| This project | HKEXnews web search | Browser automation you write | Licensed HKEx feed | |
|---|---|---|---|---|
| Bulk export | Yes | No — page-at-a-time | Yes | Yes |
| History to April 1999 | Yes | Yes, manually | Depends on your code | Yes |
| Full text of documents | Extracted from PDF/HTML/Excel | No — you open each file | You build the extractor | Varies by contract |
| Structured tables | Extracted to Markdown | No | You build it | Varies |
| Coverage verification | Per-chunk, auditable | Not applicable | You build it | Vendor SLA |
| Lands in your engine | 9 engines, any combination | No | Whatever you wire up | Usually one format |
| Speed | JSON API, no browser | Manual | Slower — renders pages | Fast |
| Cost | Free, MIT | Free | Your time | Subscription |
| Commercial redistribution | See docs/legal.md | Restricted | Restricted | Licensed |
If you need licensed, redistributable, SLA-backed data, buy the feed. If you need a complete local corpus for research, compliance, or RAG, this replaces the pipeline you would otherwise write yourself.
How It Works
flowchart LR
    A[HKEx JSON API] --> B[Phase 1: metadata]
    B --> C[Canonical record]
    C --> D{DATABASE_TARGET}
    D --> E[(PostgreSQL)]
    D --> F[(MySQL / MariaDB)]
    D --> G[(SQLite)]
    D --> H[(MongoDB)]
    D --> I[(Neo4j)]
    D --> J[(ClickHouse)]
    D --> K[(DuckDB)]
    D --> L[(SurrealDB)]
    B --> M[Graph linking]
    M --> D
    B --> N[Phase 2: download and extract]
    N --> C
Loading
- Phase 1 scrapes filing metadata through a JSF session, splitting the range into monthly
chunks and deduplicating on a 16-character MD5
filingId. - Phase 2 downloads each filing's PDF/HTML/Excel document, extracts text and tables to Markdown, and writes the payload.
- Graph linking (optional) writes
has_filingandreferences_filingedges whenCOMPANY_TABLEis set. - Failure isolation — a failure on one sink is logged and counted but never blocks another; the run exits non-zero if any configured sink failed.
Deeper detail: Architecture · ADR 0002.
HKEx API session
sequenceDiagram
    autonumber
    participant C as hkex-scraper
    participant J as HKEx site (JSF)
    participant A as HKEx JSON servlet
    C->>J: GET /search/titlesearch.xhtml
    J-->>C: HTML + javax.faces.ViewState
    C->>J: POST form (from/to dates + ViewState)
    C->>A: GET /search/titleSearchServlet.do (rowRange paging)
    A-->>C: JSON page of filings
    Note over C: generate_monthly_chunks() splits ranges > 1 month
    C->>C: dedupe on 16-char MD5 filingId
Loading
Data model
erDiagram
    COMPANY ||--o{ EXCHANGE_FILING : has_filing
    EXCHANGE_FILING ||--o{ DOCUMENT : has_document
    EXCHANGE_FILING ||--o{ EXCHANGE_FILING : references_filing
    EXCHANGE_FILING ||--o{ SCRAPE_COVERAGE : chunk_of
    EXCHANGE_FILING {
        string filingId "16-char MD5"
        string stockCode
        string title
        datetime dateTime
    }
    DOCUMENT {
        text documentText
        array documentTables
    }
    SCRAPE_COVERAGE {
        int apiCount
        int ingestedCount
        int uniqueCount
        string runId
    }
Loading
exchange_filing and scrape_coverage are SCHEMAFULL; has_filing /
references_filing are the graph edges written by graph.py.
Sink contract and read routing
flowchart LR
    CANON["canonical record<br/>per filing / document / coverage / edge"] --> DISPATCH["dispatch to every configured sink"]
    DISPATCH --> S1["sink A"]
    DISPATCH --> S2["sink B"]
    DISPATCH --> SN["sink N"]
    S1 -.->|error| LOG["logged + counted<br/>never blocks the others"]
    READ["reads: pending filings · tickers · titles · coverage"] --> FIRST["first configured sink<br/>whose capabilities include reads"]
    DISPATCH --> EXIT["sink_exit_code()<br/>non-zero if any sink failed"]
Loading
Features
- Fast API scraping — direct HKEx JSON API; no browser or Selenium.
- Full history — every filing from April 1999 to today, with chunk-level coverage checks.
- Document processing — PDF/HTML/Excel text and structured tables, extracted to Markdown.
- Multi-sink — any ordered combination of nine databases, each with native idempotent upserts.
- AI-ready — a hosted live MCP gateway plus a local stdio MCP server.
- Resumable and observable — batching, parallel downloads, stalled-job detection, per-sink
counters, and
--coverage-report/--parity-report/--verify. - Optional dependencies — the core is
requests+beautifulsoup4; drivers and document extraction are extras with graceful fallbacks.
Documentation
- Getting started · Configuration · CLI
- Database sinks (matrix) — PostgreSQL, MySQL/MariaDB, SQLite, MongoDB, Neo4j, ClickHouse, DuckDB, SurrealDB
- Live MCP gateway · AI agent support · MCP server
- Architecture · Troubleshooting · Testing
- Roadmap · De-risking register · Upgrading
- What's new · Releasing · Legal & Terms of Use · Changelog
- Docs site: https://hkex-listco-updates.ascent-partners.com/ · Try it locally (
examples/)
Development
pip install -e ".[dev,all]"
ruff check           # lint (py310, line-length 100)
ruff format --check  # formatting
pytest               # unit tests (no DB or network required)
Tests are pure unit tests; SQLite and DuckDB contract tests run in-process, and integration tests that need a server are skipped unless that sink is configured. See Testing.
Contributing
See CONTRIBUTING.md; report security issues per SECURITY.md. Ideas and questions are welcome in Discussions.
Built by Ascent Partners.
If this saves you time, a ⭐ on GitHub helps others find it.
Use with Context7
Up-to-date HKEx Filing Scraper documentation is indexed on Context7, so coding agents can pull it into context on demand. With the Context7 MCP server or ctx7 CLI installed, name the library in your prompt:
use library /simonmak-ascent/hkex-filing-scraper for API and docs
License
MIT — see LICENSE. That covers this project's code only; optional dependencies
carry their own licenses, notably the pdf extra (PyMuPDF / pymupdf4llm), which is
AGPL-3.0 and deliberately excluded from .[all]. See
docs/legal.md.
Data & Terms of Use: this is a research tool for the undocumented HKEx JSON API, and it is not affiliated with or endorsed by HKEx. Commercial redistribution of HKEx data may require a licensed HKEx feed; see docs/legal.md.
Facts
- Kind
- MCP server
- Group
- Uncategorized
- Stars
- 16
- License
- MIT
- Language
- Python
- Last push
- 2026-10-06
- Forks
- 5
- MCP Registry
- io.github.simonmak-ascent/hkex-filings
- Topics
- financial-data, graph-database, hkex, scraper, surrealdb, regulatory-filings, hong-kong-stock-exchange, postgresql, clickhouse, duckdb, mongodb, mysql, neo4j, sqlite, data-engineering, ai-agents, llm, model-context-protocol, mcp-server, ascent-data
- 1REAio.github.morluto/reaReverse engineer anything from your terminal or agent with one CLI and MCP server.125.3k
- 2com.browser-use/browser-usecom.browser-use/browser-useControl a real Chrome browser to complete any task: fill forms, extract data, book flights.117.7k
- 3World Monitorapp.worldmonitor/mcpLive markets, conflicts, country risk, chokepoints, energy, and China decision signals. 93 tools.88.3k
- 4Scrapling MCP Serverd4vinci/scrapling🕷️ An adaptive Web Scraping framework that handles everything from a single request to a full-scale crawl! Don't be shy, join here: https://discord.gg/EMgGbDceNQ and follow here for daily tips and tricks: https://x.com/Scraplingdev86.9k
- 5Everythingmodelcontextprotocol/serversThis MCP server attempts to exercise all the features of the MCP protocol. It is not intended to be a useful server, but rather a test server for builders of MCP clients. It implements prompts, tools, resources, sampling, and more to showcase MCP capabilities.85.8k
- 6Fetchmodelcontextprotocol/serversA Model Context Protocol server that provides web content fetching capabilities. This server enables LLMs to retrieve and process content from web pages, converting HTML to markdown for easier consumption.85.8k


