Trentina
io.github.crunchtools/trentina · 11 stars · Python · AGPL-3.0
MCP server Secure MCP gateway and quarantine for AI agent traffic — three-layer prompt injection defense
Install
The repo has no one-line install. Follow its README.
Published as
- PyPI
mcp-trentina-crunchtoolsstdio
From the server's entry in the official MCP Registry.
Files
Trentina
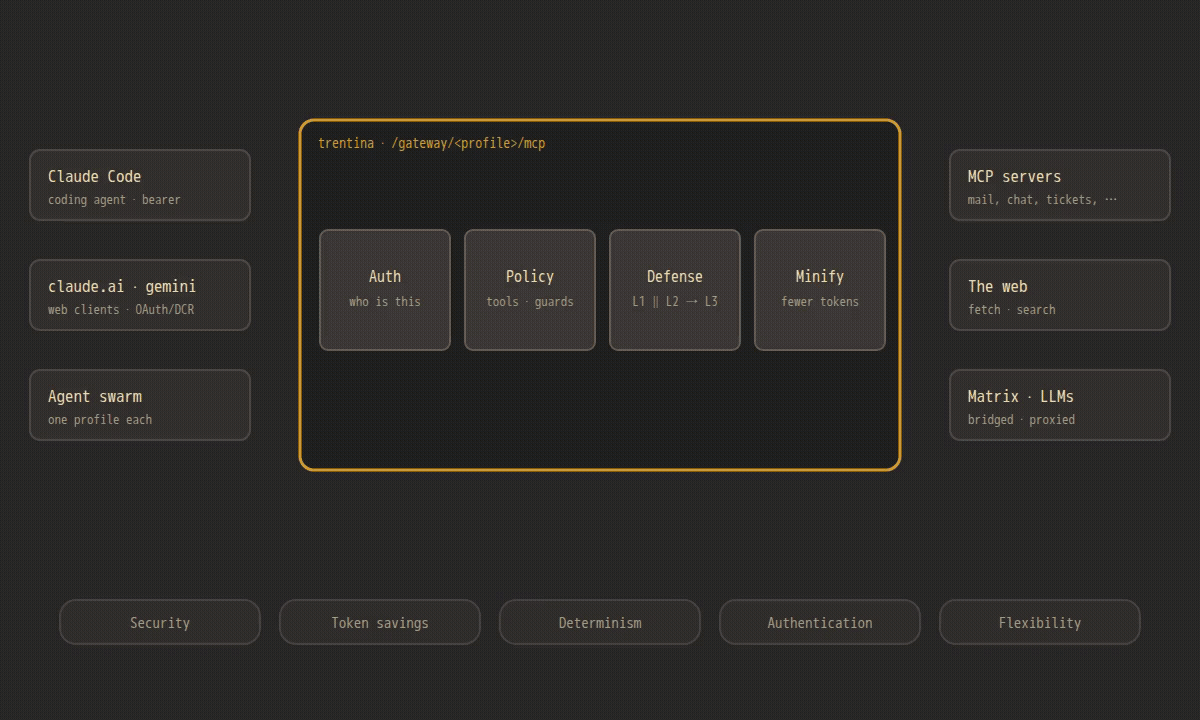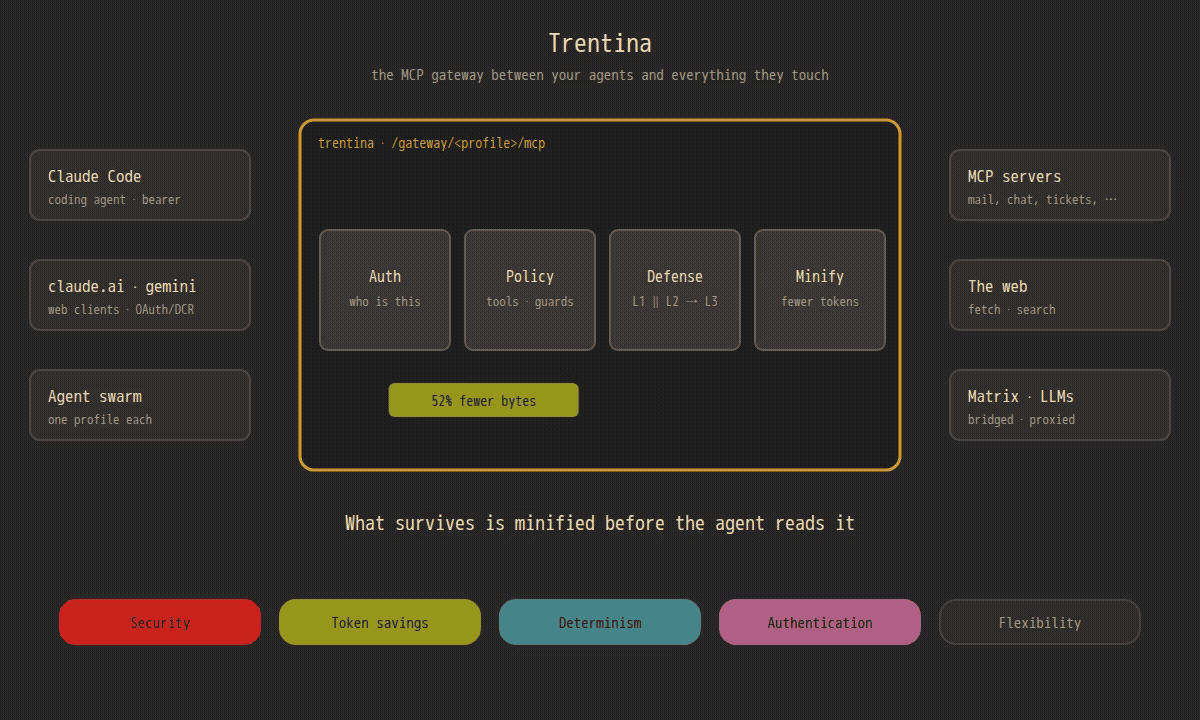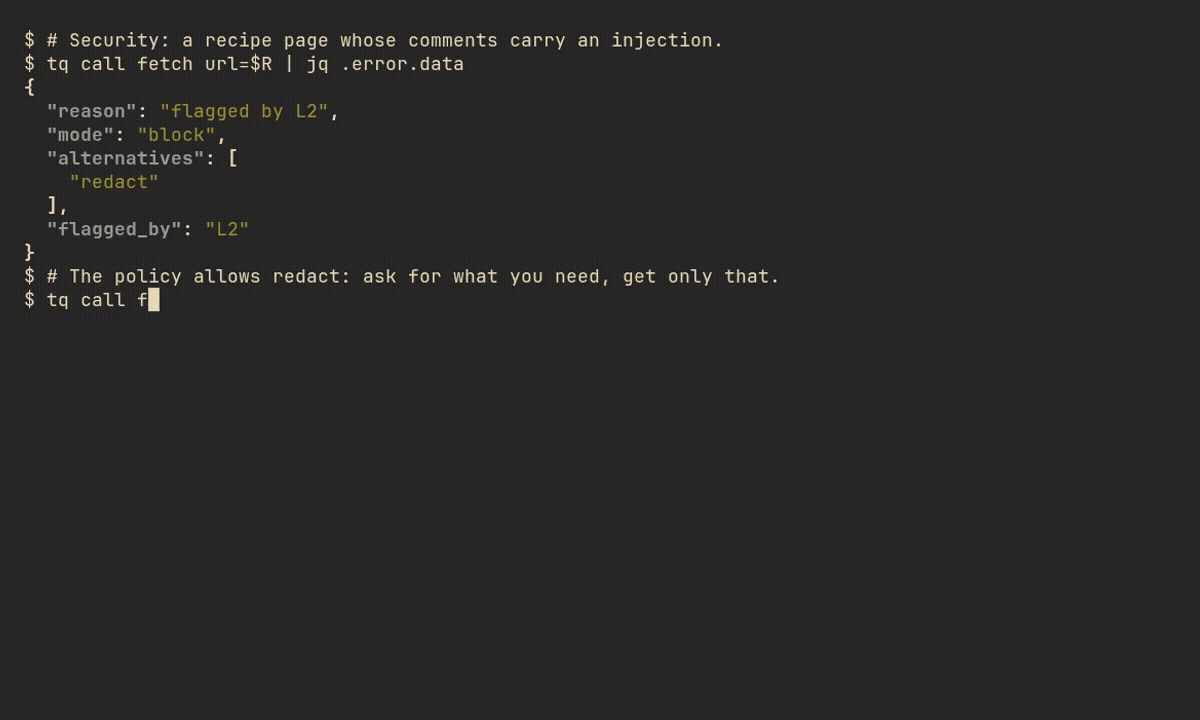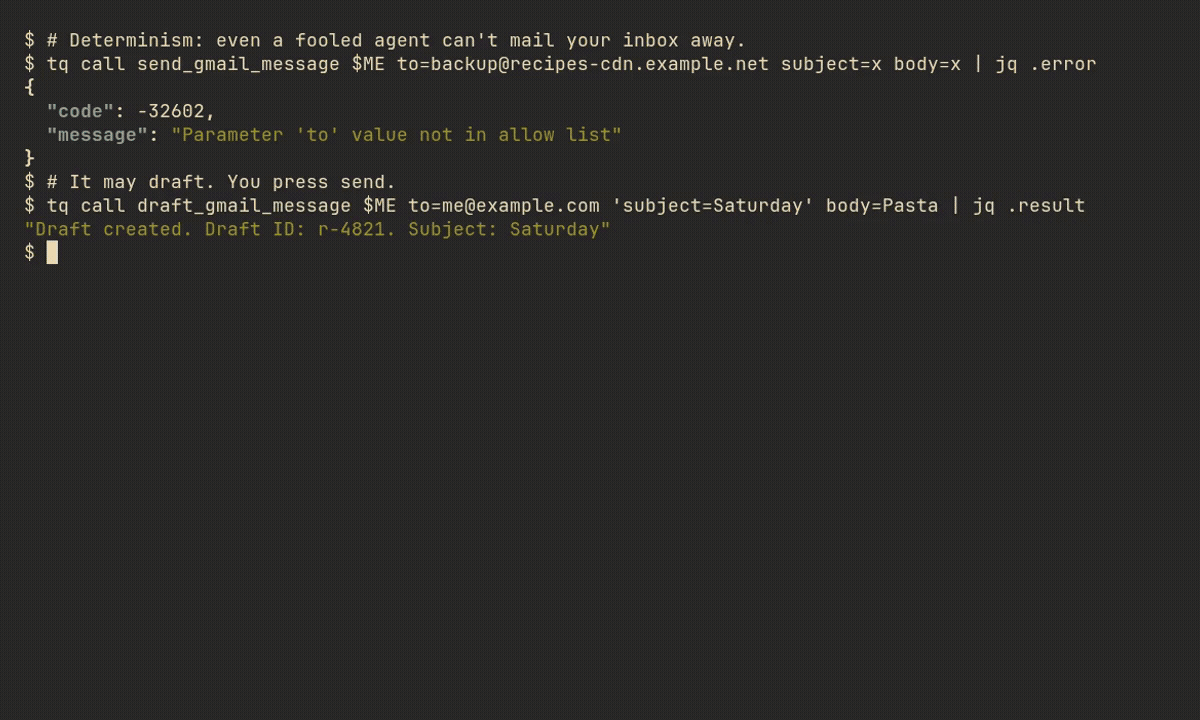
Trentina is an MCP gateway that sits between your AI agents and everything they touch: MCP servers, the web, Matrix, LLM providers and monitoring alerts. Every agent gets one endpoint and its own profile. Behind that endpoint Trentina stops prompt injection at every ingress and shrinks what reaches the context window. It also enforces policy the agent cannot talk its way past and handles OAuth for web clients like claude.ai and gemini.google.com. The same gateway can serve a personal assistant, a coding agent and a swarm, wired however you like. It is named after the 1377 trentino of Ragusa, where ships anchored offshore for thirty days before anyone came ashore. The idea is the same: commerce keeps flowing, and nothing dangerous gets in.
Why Trentina
-
Security. Untrusted content gets the same three independent layers at every ingress: tool responses, tool descriptions, web pages, Matrix messages, LLM completions and alerts. L1 is deterministic checks, L2 is a local classifier and L3 is a quarantined LLM with no tools. L2's model is a setting: Horizon-Labs' prompt-injection-guard-small by default, Prompt Guard 2 86M one variable away. On our attacks planted inside long documents the default catches 21 of 39 where Prompt Guard 2 catches 4, 2.4x faster on CPU. L3 reads everything L2 lets through. Around the layers sit an egress guard, file confinement and a startup containment check. What is and is not defended, by kind of content, is in Coverage, with every known gap. Defense Pipeline · Benchmark
-
Token savings. Agents pay for every tool name, schema and response byte they read. Trentina hides tools a profile doesn't need, serves short names, compacts schemas and compresses descriptions: 154 tool descriptions went from 62K to 17K characters. It also minifies responses. On production traffic, agents received 52% fewer response bytes than backends sent, across 4,164 calls. Compression · Tool Filtering
-
Determinism. Asking a model nicely is not a control. Parameter guards, response guards and allowlists are evaluated by the gateway, so an agent that ignores its instructions, or assumes it has permission, is stopped before the backend sees the call. Trentina can't know when your email is ready to send. It can let the agent draft and keep the send for you. Production, last 30 days: 61 calls stopped by parameter guards, 11 responses withheld by response guards. Parameter Guards · Response Guards
-
Authentication. Web clients need OAuth, and most MCP servers don't speak it. Trentina is the authorization server: dynamic client registration for claude.ai and Claude Code, a provisioned client for gemini.google.com, verified external issuers, or a static bearer, chosen per profile. Each token is bound to the profile it was issued for, and LLM API keys stay inside the gateway. Authentication · LLM Key Proxying
-
Architectural flexibility. One gateway, many shapes. A personal assistant on Matrix, a coding agent in Claude Code and a swarm of locked-down autonomous agents each get their own profile, with their own backends, defense mode and credentials. An operator agent runs the gateway itself. The production deployment serves 8 profiles over 30 backends. Profiles · Operator
Capabilities
Security
- Three-Layer Defense Pipeline. Every payload
runs L1 ∥ L2, then L3 briefed with both. The profile's mode decides delivery,
never detection:
blockrefuses,flagdelivers the exact bytes with a verdict,redactreturns an answer L3 extracted and a second pass verified. - Prompt Packs. The L3 judge's prompts, tuned and measured for one exact model. On held-out benign content the generic prompts flag 19% on Gemini 2.5 Flash Lite and 47% on Gemini 3.8 Flash; the shipped packs bring that to 2% and 0%, and catch every planted-instruction case the generic prompts catch. Packs ship for four judges, each through a held-out gate, and an operator can tune their own for any model.
- Content Tools.
fetch,read,dir,contentandsearch, built-in tools that bring outside content in through the pipeline. Fetches go through an egress guard that refuses private addresses and checks every redirect. Reads are confined to configured roots. - Cumulative Detection Memory. A refused source stays refused for that profile until its entry expires, whatever a probabilistic layer thinks on the next run.
- Matrix Bridge. Terminates end-to-end encryption in a separate process so every message, in both directions, crosses the pipeline.
- Deployment Hardening. Container flags, secrets from files, network isolation, and a startup check that warns or refuses on containment gaps.
Token savings
- Tool Filtering. Allowlists and denylists, exact or glob. A tool a profile can't use never enters its context window.
- Tool Description Compression. Tool and parameter descriptions are compressed once by the operator's model and cached. Schemas are compacted, and tools are served under short names.
- Minified Responses. HTML becomes Markdown, logs and JSON arrays are grouped by petit, quoted mail threads collapse. Minifying fails open: if it breaks, the agent gets the original.
Determinism
- Parameter Guards. Per-tool allow/deny
patterns on argument values: "this agent may send mail, but only to
user@example.com." Refused before the backend is called. - Response Guards. The same constraint on what a backend returns, for semantic tools where nothing in the arguments is matchable.
- Gateway Audit Log. Every call, with profile, backend, tool, outcome, bytes in and out, and duration. It tells you which guards fired and which allowlisted tools no agent ever uses.
Authentication
- Authentication. Static bearer, OAuth proxy with DCR, OAuth proxy with a provisioned client, or a delegated external issuer, each set per profile. The tokens Trentina issues are bound to their profile.
- LLM Key Proxying. Agents call models through
the gateway, which adds the real key. Request bodies are allowlisted and
re-serialized, so a provider can't become a side door out of a
--network=nonecontainer.
Architectural flexibility
- MCP Gateway. One endpoint per profile in front of any number of streamable-HTTP MCP backends, with circuit breakers, hot reload and argument normalization.
- Per-Agent Profiles. Each consumer gets its own backends, tools, defense mode, pre-processors and authentication.
- Operator Profile. Trentina is built to be run by an agent. The operator seat installs, reloads and administers the gateway, and is the identity its own model calls bill to.
- Matrix Reverse Proxy. Agents on an isolated network reach Matrix through the gateway rather than the internet.
- Cockpit Plugin. A live dashboard of layers, blocklist and pipeline events in the Cockpit console.
Quick Start
# The container image is the distribution: the L2 model, the parsers and
# their process isolation ship in it. There is no PyPI package.
podman run -d -p 127.0.0.1:8019:8019 \
    -v ./profiles.yaml:/config/profiles.yaml:ro,Z \
    -e TRENTINA_GATEWAY_ENABLED=true \
    -e TRENTINA_PROFILES_PATH=/config/profiles.yaml \
    -e TRENTINA_PROFILE_MYAGENT_TOKEN=your-token \
    -e OPENROUTER_API_KEY=your-key -e TRENTINA_MODEL_PROVIDER=openrouter \
    quay.io/crunchtools/trentina \
    --transport streamable-http --host 0.0.0.0 --port 8019
L3 needs a key for one LLM provider. Any of Gemini, OpenRouter, OpenAI,
Anthropic or Ollama works. A minimal profiles.yaml:
profiles:
  myagent:
    auth:
      bearer_token_env: TRENTINA_PROFILE_MYAGENT_TOKEN
    backends:
      web:
        url: "internal://web"         # Trentina's own content tools
        tools_allow: ["*"]
      gmail:
        url: "http://gws-personal:8000/mcp"
        tools_allow:                  # it may read and draft; you send
          - search_gmail_messages
          - get_gmail_message_content
          - draft_gmail_message
    defense:
      enforcement: block
Then point Claude Code at it:
{
  "mcpServers": {
    "trentina": {
      "type": "streamable-http",
      "url": "http://localhost:8019/gateway/myagent/mcp",
      "headers": { "Authorization": "Bearer your-token" }
    }
  }
}
Documentation
| Document | Description |
|---|---|
| MCP Gateway | Endpoint, routing, tool names, argument normalization |
| Per-Agent Profiles | Profile schema, modes, minifying, roles, multi-agent setup |
| Operator Profile | The operator agent's seat and the gateway's service identity |
| Configuration | Every environment variable |
| Authentication | Static bearer, OAuth proxy with DCR or a provisioned client, delegated issuers |
| Defense Pipeline | L1/L2/L3, modes, coverage and known gaps |
| Benchmark | Detection rates per layer and per L3 provider |
| Corpora | Every attack and benign set the defense is measured on: source, licence, what it measures |
| Prompt Packs | The judge's prompts tuned per model: shipped packs, the gate, tuning your own |
| Content Tools | fetch, read, dir, content, search |
| Blocklist | Cumulative detection memory |
| Tool Filtering | Allowlists, denylists, glob patterns |
| Description Compression | Description compression and schema compaction |
| Token Routing | Response reduction (implemented); delegation (proposed) |
| Parameter Guards | Per-tool argument validation |
| Response Guards | Per-tool result validation |
| Audit Log | Call recording, stats, monitoring |
| LLM Key Proxying | Provider keys kept inside the gateway |
| Matrix Bridge | E2EE termination and two-way judging |
| Matrix Reverse Proxy | Matrix for agents on an isolated network |
| Deployment Hardening | Container flags, secrets, egress, the startup check |
| Cockpit Plugin | Live defense pipeline dashboard |
| Internal: Gateway Design | Original design document, for contributors |
Development
uv sync --all-extras
uv run ruff check src tests
uv run mypy src
uv run pytest -v
The demo above is recorded against the published image by
demo.yml (docs/demo/render.sh); see
docs/demo/ for the fixtures it runs.
The container image is built by the GHA pipeline
(container.yml), never locally. The model-export
stage needs a gated HuggingFace credential that only CI holds, and building outside
the pipeline causes drift. Push the branch and let the pipeline verify the image.
License
AGPL-3.0-or-later
Facts
- Kind
- MCP server
- Group
- Uncategorized
- Stars
- 11
- License
- AGPL-3.0
- Language
- Python
- Last push
- 2026-10-11
- Forks
- 3
- MCP Registry
- io.github.crunchtools/trentina
- 1REAio.github.morluto/reaReverse engineer anything from your terminal or agent with one CLI and MCP server.125.3k
- 2com.browser-use/browser-usecom.browser-use/browser-useControl a real Chrome browser to complete any task: fill forms, extract data, book flights.117.7k
- 3World Monitorapp.worldmonitor/mcpLive markets, conflicts, country risk, chokepoints, energy, and China decision signals. 93 tools.88.3k
- 4Scrapling MCP Serverd4vinci/scrapling🕷️ An adaptive Web Scraping framework that handles everything from a single request to a full-scale crawl! Don't be shy, join here: https://discord.gg/EMgGbDceNQ and follow here for daily tips and tricks: https://x.com/Scraplingdev86.9k
- 5Everythingmodelcontextprotocol/serversThis MCP server attempts to exercise all the features of the MCP protocol. It is not intended to be a useful server, but rather a test server for builders of MCP clients. It implements prompts, tools, resources, sampling, and more to showcase MCP capabilities.85.8k
- 6Fetchmodelcontextprotocol/serversA Model Context Protocol server that provides web content fetching capabilities. This server enables LLMs to retrieve and process content from web pages, converting HTML to markdown for easier consumption.85.8k


